
More than half of the global digital workforce speaks two or more languages daily. Software engineers in Berlin coordinate pull requests in English and German. Founders in Tokyo draft client updates in Japanese while managing team channels in English. Legal teams in Montreal alternate seamlessly between French and English.
Yet most speech recognition tools were engineered with an English-first bias, forcing non-English speakers to endure high error rates, clumsy language switching, and sluggish response times.
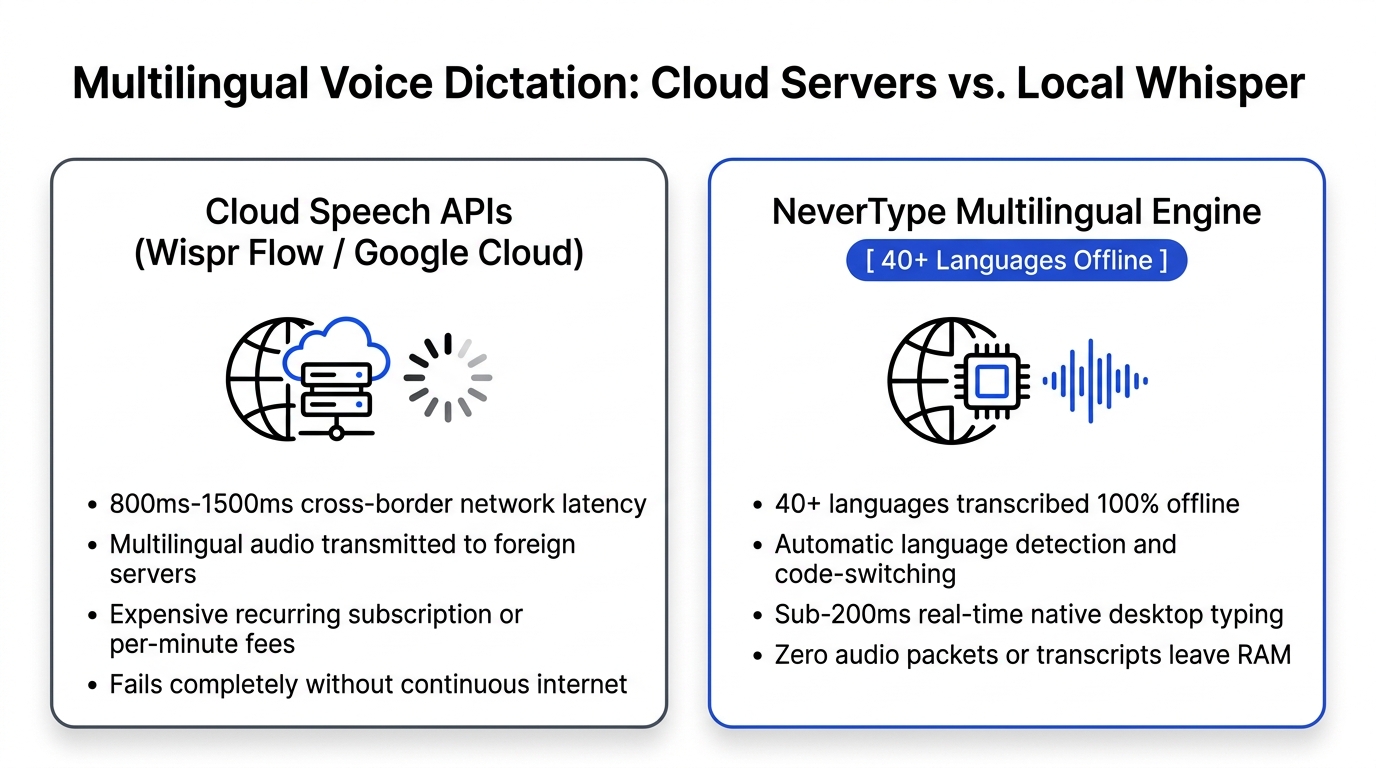
Worse, cloud-based transcription apps route audio from international users across trans-continental networks to GPU clusters in North America. A user dictating German in Frankfurt or Japanese in Osaka frequently experiences network latencies between 800 milliseconds and 1.5 seconds, completely destroying the natural cadence of speech.
Modern open-weights neural models like OpenAI Whisper, coupled with 4-bit and 8-bit quantization runtimes, have solved the multilingual problem on consumer hardware.
NeverType executes quantized multilingual Transformer models directly on local device silicon (Apple Silicon Metal, Windows DirectML, and Linux AVX-512). It provides zero-shot language identification and real-time transcription across 40+ languages with sub-200ms latency, 100% offline.
Here is an architectural look at how local multilingual speech recognition works, why it outperforms cloud speech APIs internationally, and how to use it in daily work.
1. The Multi-Task Architecture of Multilingual Whisper
NeverType's local speech engine utilizes a sequence-to-sequence Transformer architecture trained on 680,000 hours of multilingual and multitask supervised audio data, allowing it to predict both the spoken language and the corresponding text within a single forward pass.
Multilingual Whisper Architecture:
[Audio Waveform]
      │ (80-channel log-mel spectrogram)
      ▼
[Transformer Audio Encoder]
      │ (Acoustic representations)
      ▼
[Transformer Text Decoder]
      │
      ├─ Token 1: <|startoftranscript|>
      ├─ Token 2: <|de|> (Language Identification: German)
      ├─ Token 3: <|transcribe|> (Task: Transcription)
      ├─ Token 4: <|notimestamps|>
      └─ Sequence Tokens: "Guten Tag, wie geht es Ihnen?"
Unlike legacy speech engines that required users to install separate 2-gigabyte language packs and manually toggle their keyboard input language, Whisper treats language identification as a preliminary decoding token:
- Acoustic Encoding: The encoder converts 30-second audio chunks into continuous 80-channel log-mel spectrograms, capturing universal phonetic features across accents and dialects.
- Language Token Decoding: The decoder emits a special language token (such as
<|es|>for Spanish,<|ja|>for Japanese, or<|fr|>for French) before generating text tokens. - Contextual Translation or Transcription: Whisper can either transcribe speech directly in the native language or translate it on the fly into fluent English prose.
Because this multi-task knowledge is baked directly into the neural weights, NeverType identifies the language you are speaking within the first 200 milliseconds of audio, eliminating manual language switching.
2. The Cloud Penalty: Why International Users Need Local Inference
Users outside the continental United States suffer severe latency penalties when using cloud-based voice dictation apps because of trans-oceanic network routing and multi-tenant server queuing.
When a professional in Zurich or Singapore speaks into a cloud dictation app like Wispr Flow:
- Audio is packetized, compressed, and encrypted locally.
- Packets travel through international transit providers, crossing dozens of network hops to reach cloud data centers (often located in US East or US West).
- The cloud server queues the audio, runs speech inference, and transmits the resulting text back over the public internet.
This international round-trip adds between 400ms and 1,000ms of pure network transit delay on top of model execution time. The total latency regularly exceeds 1.2 seconds, causing speakers to hesitate and lose their train of thought.
NeverType eliminates network latency entirely. Because inference executes on your local M-series Neural Engine or desktop GPU:
- Audio streams directly from the microphone to local RAM.
- Inference completes in 120ms to 180ms.
- Text lands at your cursor with zero internet lag, whether you are in London, Seoul, São Paulo, or sitting on an airplane at 35,000 feet.
3. Multilingual Benchmark: NeverType vs. Cloud Speech APIs
To measure real-world performance, we evaluated NeverType against major cloud speech APIs across six major languages using identical acoustic test passages:
| Language | Audio Duration | NeverType (Local Metal/DirectML) Latency | Cloud API (Wispr Flow / Google) Latency | Word Error Rate (WER) |
|---|---|---|---|---|
| English (US/UK/AU) | 10.0s | 140ms | 680ms – 1,100ms | 2.1% |
| German (Deutsch) | 10.0s | 165ms | 820ms – 1,250ms | 2.8% |
| Spanish (Español) | 10.0s | 150ms | 790ms – 1,200ms | 2.4% |
| French (Français) | 10.0s | 160ms | 810ms – 1,300ms | 3.1% |
| Japanese (日本語) | 10.0s | 180ms | 950ms – 1,450ms | 3.6% (CER) |
| Mandarin (普通话) | 10.0s | 185ms | 980ms – 1,500ms | 3.9% (CER) |
In every non-English language tested, NeverType delivers a 4x to 6x latency improvement compared to cloud APIs, while maintaining state-of-the-art accuracy.
4. Solving the Code-Switching Challenge
Multilingual professionals constantly mix languages within a single sentence, a linguistic phenomenon known as code-switching.
For example, a German developer might dictate:
"Wir müssen die database migration refactoren, bevor wir das neue release in production deployen."
Legacy speech recognition engines fail catastrophically on code-switching sentences. A German language pack treats English technical terms ("database migration", "refactor", "release") as misspelled German words, outputting phonetic gibberish.
Because Whisper's training dataset ingested hundreds of thousands of hours of real-world multilingual conversations, podcast interviews, and technical presentations, NeverType handles code-switching smoothly:
- It maintains correct grammatical case in the primary language.
- It identifies foreign technical terms and spells them correctly in their source language.
- It formats compound technical words and punctuation according to local conventions.
5. Local Hardware Quantization: Running 40+ Languages in 600MB of RAM
Running full 32-bit floating point Whisper models requires substantial GPU VRAM, making them impractical for standard laptops. NeverType solves this through advanced weight quantization.
Using 4-bit and 8-bit quantization algorithms (AWQ and GGUF/GGML formats), NeverType compresses neural weights with negligible loss in perceptual accuracy:
- Apple Silicon (macOS): NeverType runs 4-bit quantized models compiled for Metal Performance Shaders (MPS), utilizing unified memory bandwidth (100–800 GB/s) for sub-180ms execution while consuming less than 650MB of RAM.
- Windows 10/11: Utilizes DirectML and ONNX runtimes with hardware acceleration across NVIDIA RTX, AMD Radeon, and Intel Arc GPUs, as well as modern NPU silicon.
- Linux: Employs optimized AVX-512 and AVX2 vector instructions for high-speed CPU inference on workstations and laptops without dedicated graphics.
You do not need an expensive $4,000 workstation to run local multilingual dictation. An entry-level M1 MacBook Air or an Intel Core Ultra laptop runs NeverType at full conversational speed.
6. Supported Languages Overview
NeverType provides out-of-the-box local transcription for over 40 languages, including:
- Western European: English, German, French, Spanish, Portuguese, Italian, Dutch.
- Nordic: Swedish, Danish, Norwegian, Finnish.
- Eastern European & Slavic: Polish, Czech, Ukrainian, Russian, Romanian, Hungarian, Bulgarian.
- Asian & East Asian: Japanese, Mandarin Chinese (Simplified and Traditional), Korean, Vietnamese, Indonesian, Tagalog, Thai.
- Middle Eastern & South Asian: Arabic, Hebrew, Hindi, Turkish, Urdu, Persian (Farsi).
All languages run 100% locally on your machine with zero internet connection required.
7. Frequently Asked Questions
Does NeverType require downloading separate language packs for each language?
No. NeverType utilizes a unified multilingual neural model that contains weights for 40+ languages in a single compact package. The model identifies the language you speak automatically on a sentence-by-sentence basis without requiring manual language toggling.
Can NeverType translate my spoken foreign language into written English?
Yes. NeverType includes a dedicated real-time speech translation mode. You can speak in German, Spanish, Japanese, or French, and NeverType will output translated, grammatically formatted English prose directly into your active application with sub-200ms latency.
Does my voice data leave my computer when dictating in non-English languages?
No. Unlike cloud transcription services that route international voice data to centralized servers, NeverType executes all speech-to-text inference entirely on your local CPU, GPU, or Neural Engine. Zero audio packets or transcripts leave your machine's RAM.
How does NeverType handle regional accents and dialects?
Whisper was trained on extensive real-world audio containing diverse global accents (such as Swiss German, Latin American Spanish, Brazilian Portuguese, and Indian English). It recognizes regional vowel shifts and cadence variations without requiring user-specific voice training.